
The index
Every Git tutorial tells you to run git add before git commit, and most of them describe git add as "staging" a file. Very few explain what that actually means, which is a shame, because the index (also called the staging area, or the cache) is the key to a lot of Git behaviour that otherwise seems arbitrary.
Here's the short version: the index is the tree that your next commit will have. It's stored in a single binary file, .git/index, and git ls-files --stage will show you what's in it.
$ ls -l .git/index-rw-r--r-- 1 demo demo 137 Sep 29 00:23 .git/index$ git ls-files --stage100644 9761654c68d36874ac2184210502a0d2d116e817 0 README
That should look familiar. The index is a flat list of the same information a tree object holds: a mode, a blob hash, and a path for every tracked file. (The 0 is the "stage number", which is only used during merge conflicts.) When you run git commit, Git turns this list into tree objects and points a new commit at the root. It doesn't look at your working tree at all.
This means Git is really juggling three trees at any given time:
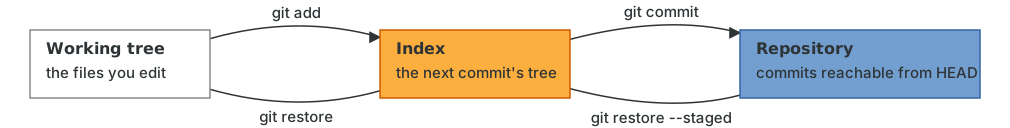
- The working tree, which is the files you can see and edit.
- The index, which is the proposed next commit.
- The repository, or more specifically the tree of the commit that
HEADpoints to, which is the last commit.
git status is a report on the differences between these three trees. git diff compares the working tree with the index, and git diff --staged compares the index with HEAD. Let's watch it happen.
$ echo 'Some more information here.' >> README$ git status --shortM README$ git ls-files --stage100644 9761654c68d36874ac2184210502a0d2d116e817 0 README
We've changed the readme, and git status shows an M in the second column, meaning the working tree differs from the index. The index itself hasn't changed: it still points at the old blob. Now let's add the file.
$ git add README$ git ls-files --stage100644 a5f1c30be4eb55f726d2cd0839937f3b672c8862 0 README$ find .git/objects -type f.git/objects/9d/073fcdfaf07a39631ef94bcb3b8268bc2106b1.git/objects/a5/f1c30be4eb55f726d2cd0839937f3b672c8862.git/objects/39/f6ea2439eb1fd9f7837a223866f243b70125c0.git/objects/97/61654c68d36874ac2184210502a0d2d116e817
Two things happened. The index entry for README now points at a new blob, a5f1c30. And that blob has been written to .git/objects, even though we haven't committed anything. git add doesn't just mark a file as "to be committed"; it stores the file's content in the repository right then and there. This is why a staged change survives almost any accident short of deleting .git, and it's something we'll take advantage of in Recovering lost commits.
$ git status --shortM README$ git diff$ git diff --stageddiff --git a/README b/READMEindex 9761654..a5f1c30 100644--- a/README+++ b/README@@ -1 +1,2 @@This is the readme.+Some more information here.
The M has moved to the first column: the index now differs from HEAD, and the working tree matches the index. git diff shows nothing while git diff --staged shows the change. If you've ever been confused by git diff printing nothing when you know you changed a file, this is why.
Unstaging
The opposite of git add is git restore --staged, which copies the entry for a path from HEAD back into the index without touching the working tree.
$ git restore --staged README$ git ls-files --stage100644 9761654c68d36874ac2184210502a0d2d116e817 0 README$ git status --shortM README
Older guides will tell you to use git reset HEAD README for this, and that still works. git restore was introduced in Git 2.23, along with git switch, to split the overloaded git checkout command into two commands that each do one thing. git restore <file> (without --staged) copies the index version of a file into the working tree, discarding your changes, so be careful with it.
Building a commit by hand
The first edition of this guide said that you could use Git's low-level commands to build a commit manually, but that it was beyond the scope of the guide. It turns out to be only four commands, and doing it once makes the relationship between the index, trees and commits click in a way that no diagram can.
First, we update the index. git update-index is the plumbing command that git add is built on.
$ git update-index --add README$ git ls-files --stage100644 a5f1c30be4eb55f726d2cd0839937f3b672c8862 0 README
Next, we turn the index into a tree object. We saw write-tree in Tree objects.
$ git write-treeb86d3aec42b0b01b7091585a18208689a9b8b4f3
Now we create a commit object that points at that tree, with the current commit as its parent. commit-tree reads the author and committer from your configuration and the message from -m, and prints the hash of the new commit.
$ git commit-tree b86d3ae -p HEAD -m 'Update README (by hand)'29bb0554dd9c71bec88701d76d3b3ab309942aa8
We have a commit. But git log doesn't know about it.
$ git log --oneline39f6ea2 First commit
This is the last piece of the puzzle: a commit that no branch points to is invisible to most of Git. The final step of git commit is to move the current branch to the new commit, and git update-ref does exactly that.
$ git update-ref refs/heads/main 29bb0554dd9c71bec88701d76d3b3ab309942aa8$ git log --oneline29bb055 Update README (by hand)39f6ea2 First commit$ git status --short
A clean working tree and a new commit, without ever running git commit. Now that we've seen how branches are updated, it's time to look at what they are.